Communication Products
Optical Transceivers · Telecom Synchronization · Network Infrastructure · Custom Solutions
A training cluster is not a general purpose network with more bandwidth bolted on. The back-end fabric connects accelerators to each other, the traffic is collective, and one slow or flapping link slows the whole job rather than one conversation. That is why the fabric is built as a flat, high radix topology with a fixed number of links per node, and why the optics in it are chosen once and then kept uniform.
This guide covers the optical links inside that fabric: node to leaf, leaf to spine, and the storage and management networks alongside them. Links that leave the building are covered on the 800G AI data centre interconnect guide.
Two forces push a cluster to 800G per port. The first is the link count: an accelerator server with several network ports multiplies into a fabric where every leaf port matters, so a higher rate per port keeps the switch count, the rack unit count and the cable volume down. The second is the switch side: a fixed number of cages per chassis is filled with the fastest port the fabric will carry for the life of the cluster, and the tier behind it can then break out to lower rates.
Uniformity matters more here than in a best effort network, because a training job is sensitive to link flaps and to any asymmetry in the path. A mixed inventory of modules of unknown age and unknown coding is usually where that uniformity is lost.
| Link in the cluster | Module | Rate | Media / wavelength | Reach class |
|---|---|---|---|---|
| Node to leaf, same rack | DAC or AEC assembly | 400G / 800G | Copper, passive or active | A few metres |
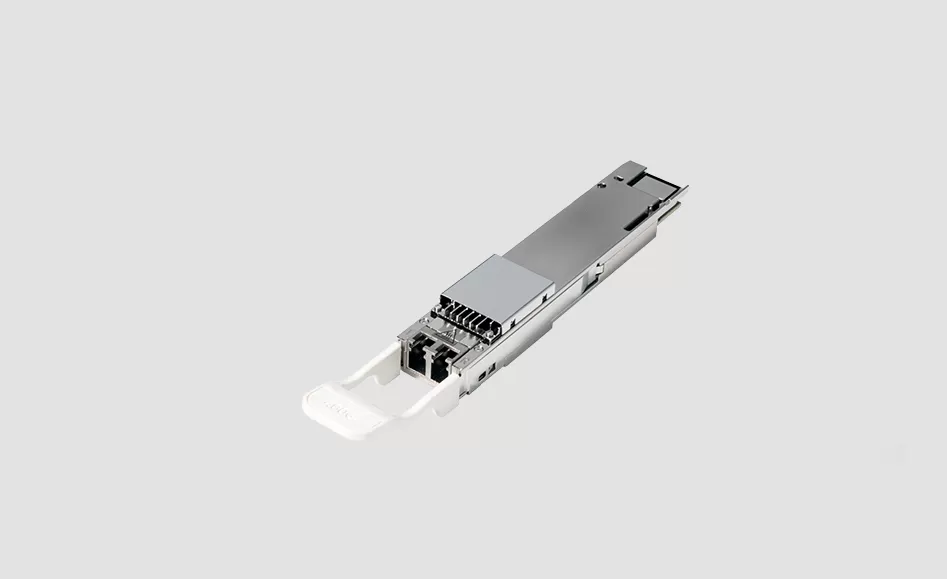
| Node to leaf, same row | 800G SR8 or SR4 parallel | 800G | MMF, 850 nm parallel | 50 to 100 m |
| Node to leaf, single-mode plant | 800G DR8 | 800G, 8 x 100G | SMF, parallel 1310 nm | 500 m class |
| Leaf to spine, same hall | 800G DR8 | 800G, 8 x 100G | SMF, parallel 1310 nm | 500 m class |
| Leaf to spine, hall to hall | 800G 2xFR4 | 800G, 2 x 400G | SMF, CWDM or LAN-WDM | 2 km class |
| Storage and front-end network | 400G QSFP-DD DR4 / FR4 | 400G | SMF, parallel or CWDM | 500 m to 2 km |
| Campus or metro extension | 400G / 800G ZR and ZR+ coherent | 400G or 800G | SMF, DWDM C-band tunable | Campus to metro |
The reach column lists the standard classes behind each code; the working limit is the measured loss after patch panels and cassettes. Form factors and reach codes are on the 800G transceiver page, the tier below on the 400G QSFP-DD and OSFP page, and the coherent side on coherent optics.
Inside a rack, copper is the cheapest and lowest power connection, so DAC assemblies stay first choice for the shortest runs. Once a link crosses more than a rack or two, reach, bend radius and cable volume work against copper: a heavy bundle of trunks in front of the ports blocks airflow and makes the rack hard to service. Active electrical cables cover runs that are too long for passive copper but too short to justify optics, and optics take over where the run leaves the row or crosses a hall. Fix that break point by distance and airflow, and put it in the cabling plan at the start.
Collective traffic over remote direct memory access is lossless and latency sensitive, which puts two requirements on the optical layer. The forward error correction profile has to be the same at both ends and along the whole path, because a mismatch shows up as a link that comes up but never carries the job at full rate. The latency class and mode set then have to match what the switch and the network interface expect, which is why the firmware release belongs in the request. Keep one rate per path as well: a 400G link inside an 800G path costs more in fault finding than the module it saved.
The optics have to be supported by the host port, coded for the platform you name, and readable through it, so that power, temperature and alarms can be watched from the switch. Optics supplied for branded switches are compatible parts coded for the platform you name, tested against the port, and are not manufactured by the brand of the host. Name the platform, the firmware release and the rate mode, and say whether the far end will be a different vendor, since that decides the coding. Platforms common in these fabrics include Mellanox, Arista, Cisco and Juniper. Hold spares per link type and per rate: a training fabric goes down on the type it cannot replace that day.
Is copper still usable in an 800G cluster?
Yes, for short in-rack runs. Passive copper is first choice to the top of rack, active electrical cables cover the longer in-row runs, and optics take over once the link leaves the row.
Which 800G module goes between leaf and spine?
DR8 for the 500 m parallel class inside a hall, and 2xFR4 for the 2 km class where a duplex pair already exists between halls. The switch port and the cabling decide.
Does a cluster need industrial temperature optics?
Not for the grade itself, since the equipment sits in a conditioned hall. Airflow matters instead: a high density rack with poor airflow runs its optics hot, so module temperature has to be readable through the switch.
Can a cluster mix vendors at the two ends of a link?
Usually yes, when each end is coded for its own host and the rate, FEC and mode set match. Say in the request that the far end is a different platform, because that decides the coding.
What has to be in the request for a cluster build?
The topology and links per node, the rate per tier, the measured runs, the switch platform and firmware, the cabling available, and the power and airflow limits of each rack.
Send the topology, the rate per tier, the measured runs and the switch platform and firmware, and we confirm the module, the reach code and the coding for each link type. Related reading: the AI training cluster DWDM interconnect page for wavelength level capacity, the 400G to 800G migration guide for a staged refresh, and all optics selection guides.
APEX is a communication technology brand focused on optical transceivers, telecom synchronization products, and network infrastructure equipment. We provide products and engineering support for telecom operators, data centers, mobile networks, and enterprise customers worldwide.
APEX GROUP is headquartered in Hong Kong, with our core team and supply chain operations based in China. We ship to customers across Asia, the Middle East, Europe, Africa, and the Americas.
We are a brand owner with deep engineering partnerships. We control product design, specification, quality validation, and supply chain management. Our products are built to our specifications by qualified manufacturing partners, and we handle all testing, coding, and quality assurance before shipment.
Yes. We code transceivers to match the host platform requirements of major switch and router vendors including Cisco, Juniper, Arista, HPE, Huawei, Nokia, and others. Tell us your platform model and required OS version, and we will ship modules that are recognized natively by your equipment.
Datasheets, compatibility matrices, and S-parameter reports are available for all standard products. Contact our sales team or visit the product pages on our website to request documentation.
Provide us with your switch make, model, and OS version. We code the transceiver firmware accordingly before shipment. If you are testing for the first time, we recommend ordering a sample unit to validate compatibility in your specific environment before placing a volume order.
Switch vendors occasionally introduce transceiver whitelisting in new OS releases. We track major platform updates and can provide recoded firmware matching the new OS requirements. Contact technical support if your existing APEX modules stop being recognized after a switch upgrade.
Contact our sales team by email, WhatsApp, or WeChat with your part number and quantity. We will confirm pricing, lead time, and shipping options. For first-time customers, we typically recommend starting with a sample order to validate compatibility before scaling to production volumes.
We ship via DHL, FedEx, and UPS for express delivery, typically 3-7 business days to most destinations. For volume orders, we also offer air freight and sea freight options. We can ship on your courier account or ours, and we handle all export documentation.
Sample orders start from 1-2 units for evaluation. For production orders, MOQ varies by product type, typically 10-50 units for standard transceivers. Contact us for specific product MOQs.
We accept wire transfer (T/T) as our standard payment method. For established customers, we can offer net-term payment arrangements. Contact our sales team to discuss payment terms.
All APEX products come with a 3-year standard warranty against manufacturing defects. We offer advance replacement for defective units, shipping the replacement before you return the failed unit to minimize downtime. For full details, visit our After-Sales Service page.
Contact us by email, WhatsApp, or WeChat. Describe your issue with as much detail as possible, including switch model, OS version, transceiver part number, and the problem you are seeing. Our support engineers will respond within one business day.
Yes, we strongly encourage sample testing. Order 1-2 units of each model you plan to deploy. Test them in your switches with your fiber plant and traffic load. Once validated, we can proceed with production quantities.
Yes. Many of our customers are telecom operators and government networks requiring 5-10 year supply continuity. We offer lifecycle management commitments with advance notification of any changes. See our Global Supply Chain page for details on long-term supply programs.
APEX GROUP LIMITED
Phone: 85298213834
WhatsApp: 85298213834
Email: Info@apexallinone.com